Hindi in old fonts, converted: two samples, measured
Two PDFs typed in the Kruti Dev font, put through IndicPDF’s Legacy PDF to Word tool and then Word to EPUB. Below: a picture of each original, the text you get when you copy from it, the Unicode that came out, and what we counted. You can download the original PDFs too; the Word and EPUB files are the tool’s own output, unedited.
Sample 1: a short story set as a book
Premchand’s story ईदगाह (Idgah), set as a 12-page A5 book in Kruti Dev 010 — title page, chapter heading, running head, page numbers, a footnote — and exported from Microsoft Word with the font embedded.
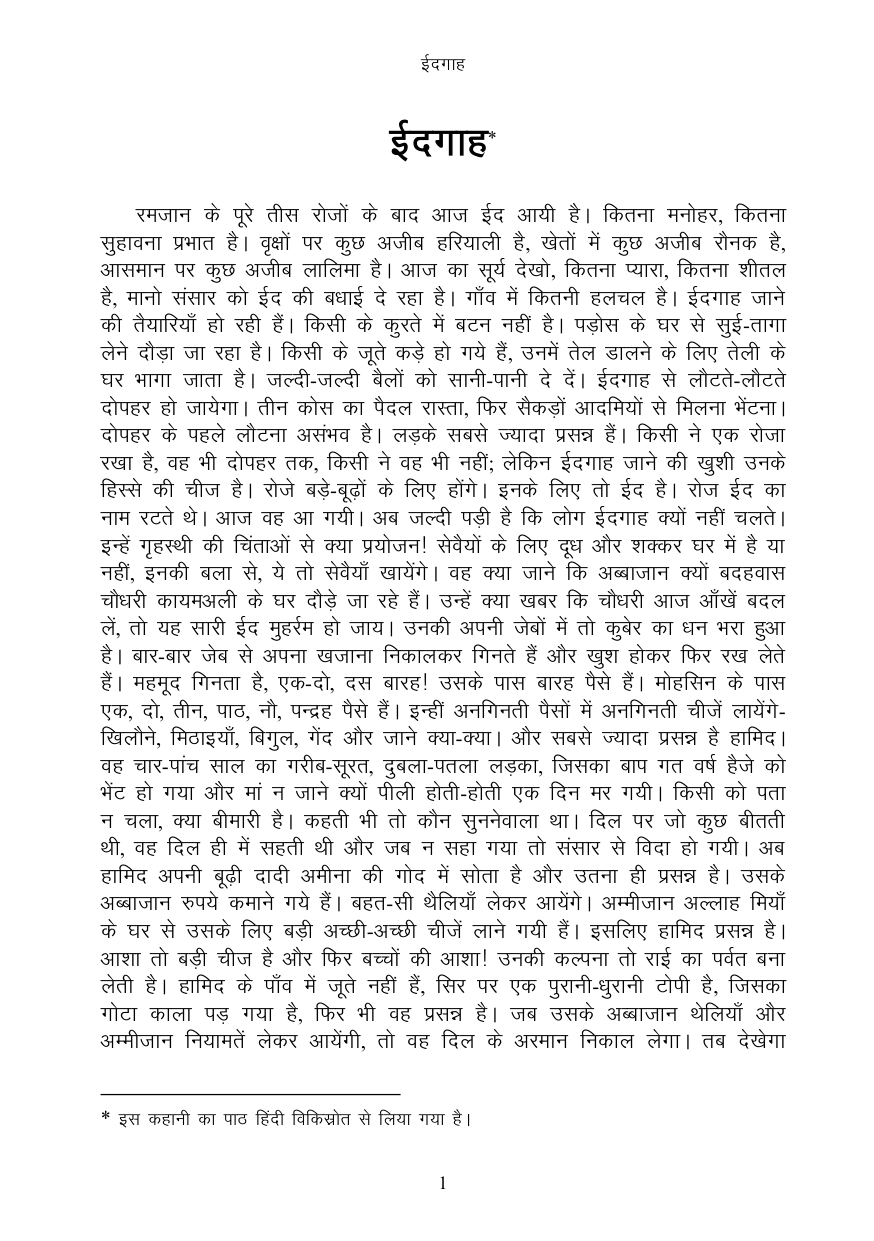
What copying from the PDF gives you
jetku ds iwjs rhl jkstksa ds ckn vkt Ãn vk;h gSA fdruk euksgj, fdruk lqgkouk izÒkr gSA
What IndicPDF wrote (Unicode)
रमजान के पूरे तीस रोजों के बाद आज ईद आयी है। कितना मनोहर, कितना सुहावना प्रभात है।
Measured against the source text
99.979%
of characters match (5 differences in 23,985)
99.897%
of words match (5 of 4,866)
We typeset this demo file ourselves: IndicPDF wrote the Kruti Dev bytes and IndicPDF read them back, through the same font table both ways, so a mistake in that table would not show in this figure. Sample 2 is a real document we did not make.
The 5 differences: 3 Devanagari digits (२, ३) came out as Western digits, because our typesetting wrote them that way and the PDF prints 2 and 3; and 2 invisible joiner characters in the source text, which draw nothing, were dropped.
Sample 2: a government Act from an official gazette
10 pages of a 2016 state Act as printed in the state’s official gazette, typed in Kruti Dev, with figures set in an English font. Government Acts may be reproduced in India.
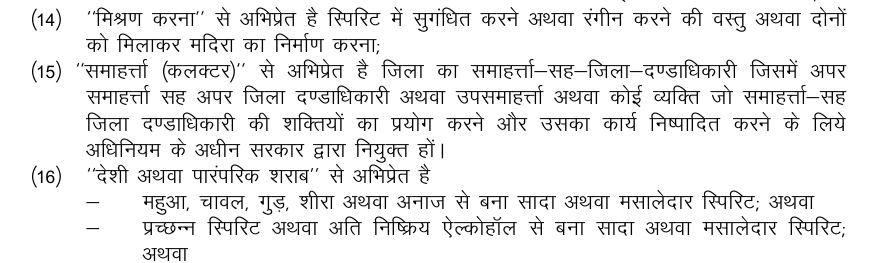
What copying from the PDF gives you
¼14½ ^^feJ.k djuk** ls vfHkizsr gS fLifjV esa lqxaf/kr djus vFkok jaxhu djus dh oLrq vFkok nksuksa dks feykdj efnjk dk fuekZ.k djuk(
What IndicPDF wrote (Unicode)
(14) ‘‘मिश्रण करना’’ से अभिप्रेत है स्पिरिट में सुगंधित करने अथवा रंगीन करने की वस्तु अथवा दोनों को मिलाकर मदिरा का निर्माण करना;
What we counted on both sides
There is no reference text for this document, so it has no accuracy figure. These are the counts IndicPDF makes on the PDF and on the Word file it wrote:
| Characters, page by page | 25,674 in the PDF, 25,674 in the Word file, none missing |
|---|---|
| Numbers | 245 of 247 identical; the other 2, 0.5% and 0.05%, are in the Word file as printed — our check counted the % sign apart |
| Clause markers such as (14) | 111 of 111 |
| Section numbers | 29 of 29 |
Five words carry sign sequences our spelling check flags for a proofreader. These counts show that nothing was dropped between the PDF and the Word file, not that every letter is right: only a reader comparing the pages with the print can say that.
The EPUB files
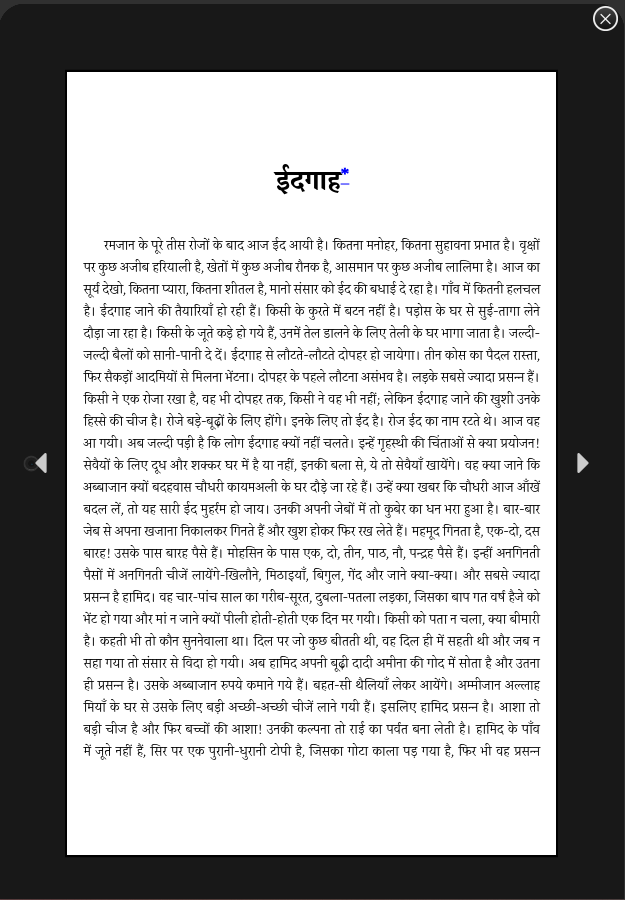
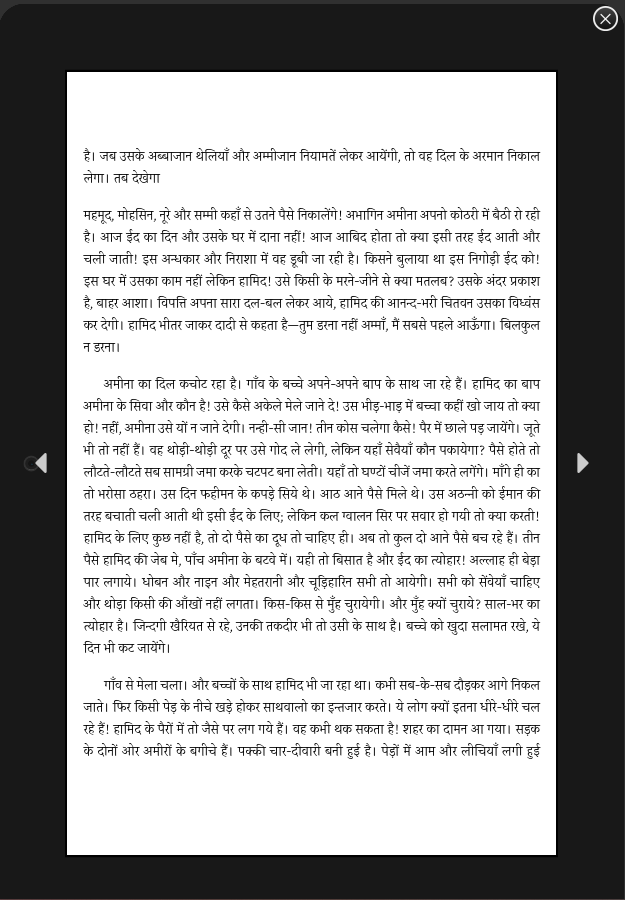
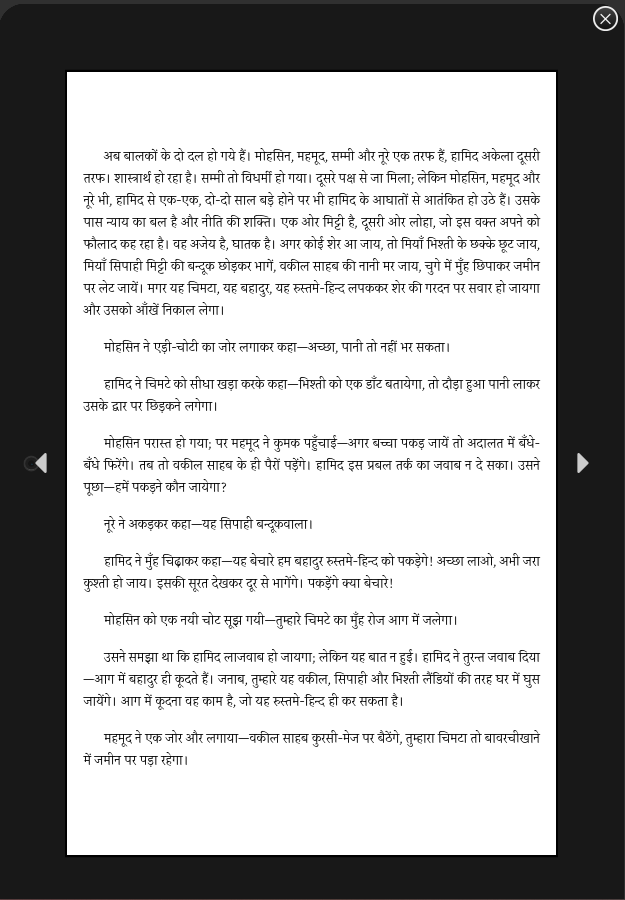
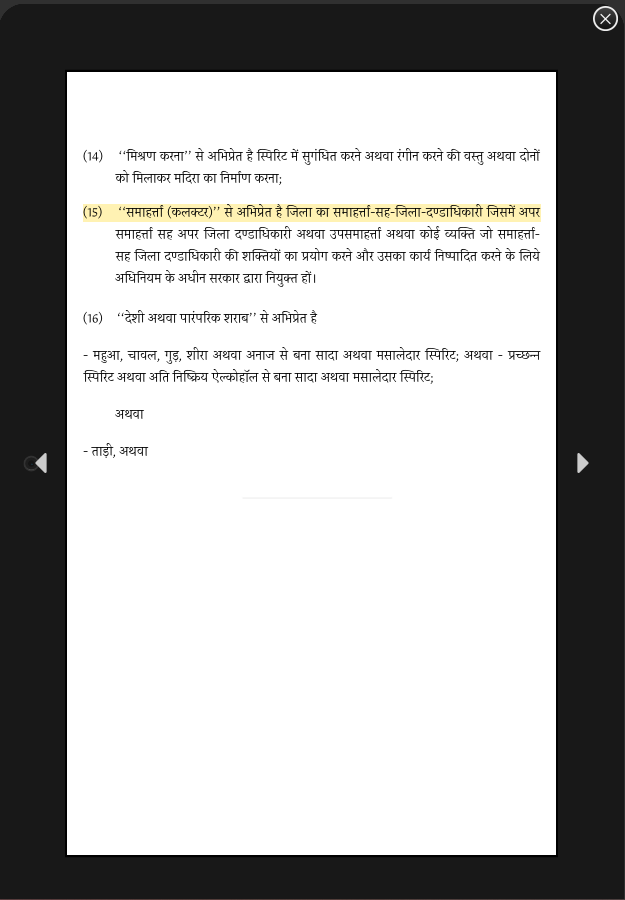
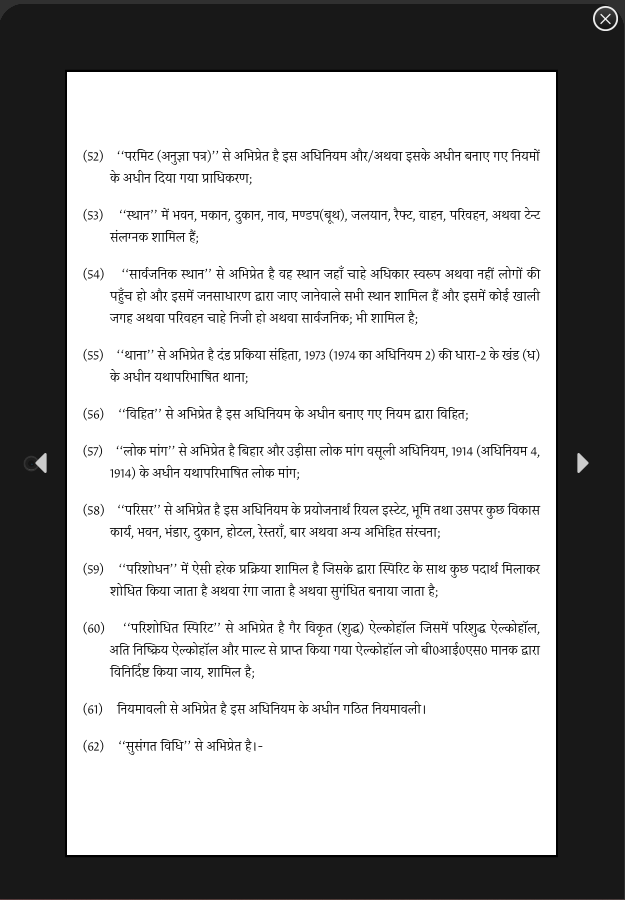
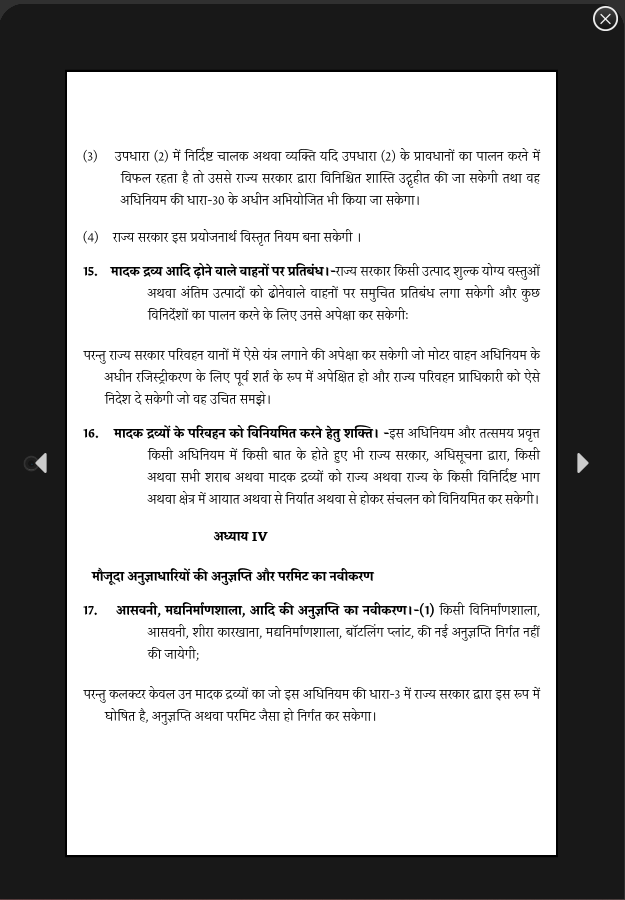
Both EPUBs pass EPUBCheck 5.1 with no errors and no warnings. Kindle Previewer 3 converted both with 0 errors and 0 quality issues; the pages below are its tablet preview.
How it was measured
The story’s Word file was compared with the Wikisource text it was typeset from, after Unicode normalisation (NFC), ignoring line breaks and runs of spaces. Differences are counted as edits: one wrong, missing or extra character is one character difference, and the same for words. The title page, the footnote mark and the running heads are left out because they are not the story. Every difference is listed in the report we kept.
Try it on your own books
Without an account, up to 10 pages a file.