Indic File Converter
For Indian Languages
Convert PDF, Word, text, spreadsheet, slide and image files, read scans in 12 Indian languages and English, and turn legacy-font text into Unicode. Files are stored encrypted and deleted within 4 hours.
Convert Your PDF with Ease
Drag & Drop or Click to Upload Your File
How it works
Three steps, the same for every tool. Shown here with PDF to DOCX.
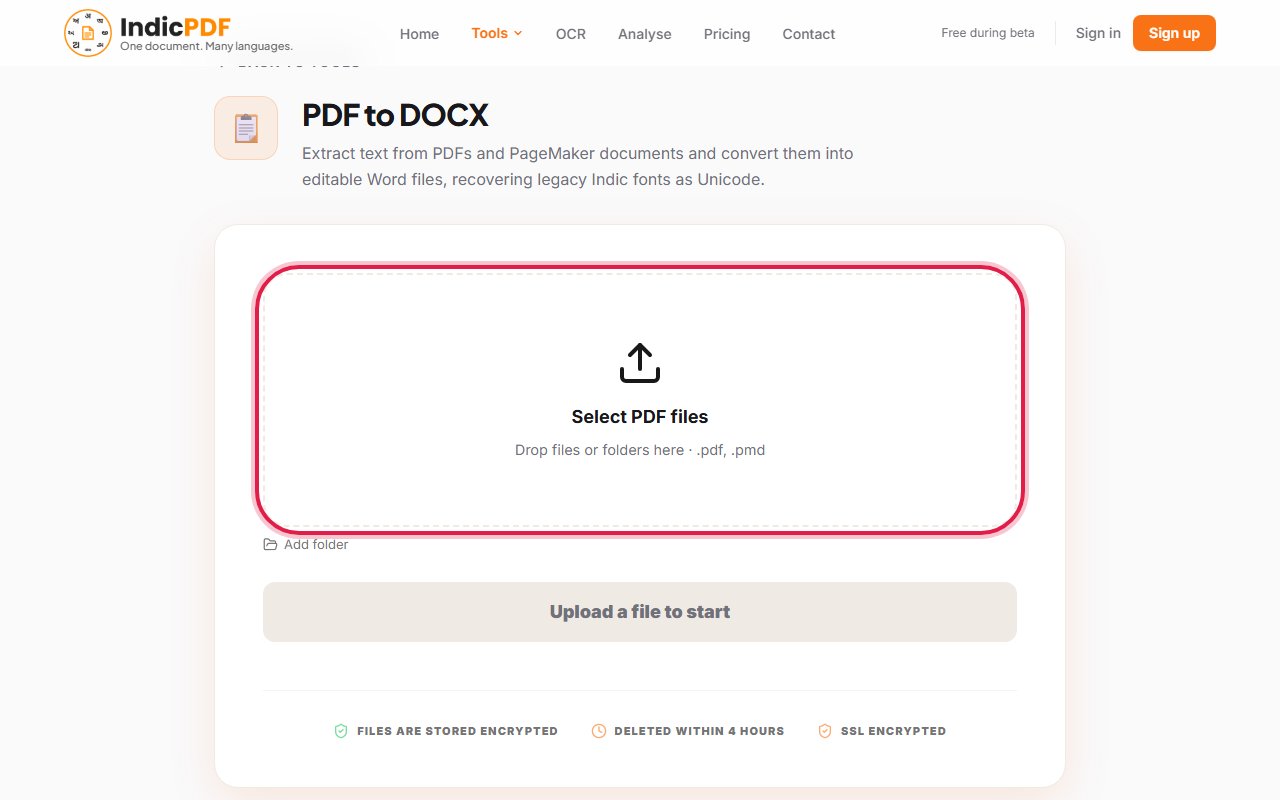
Step 1
Choose your file
Pick the tool for the job and drop in a PDF, Word file, PageMaker publication or scan. Nothing to install and no account needed.
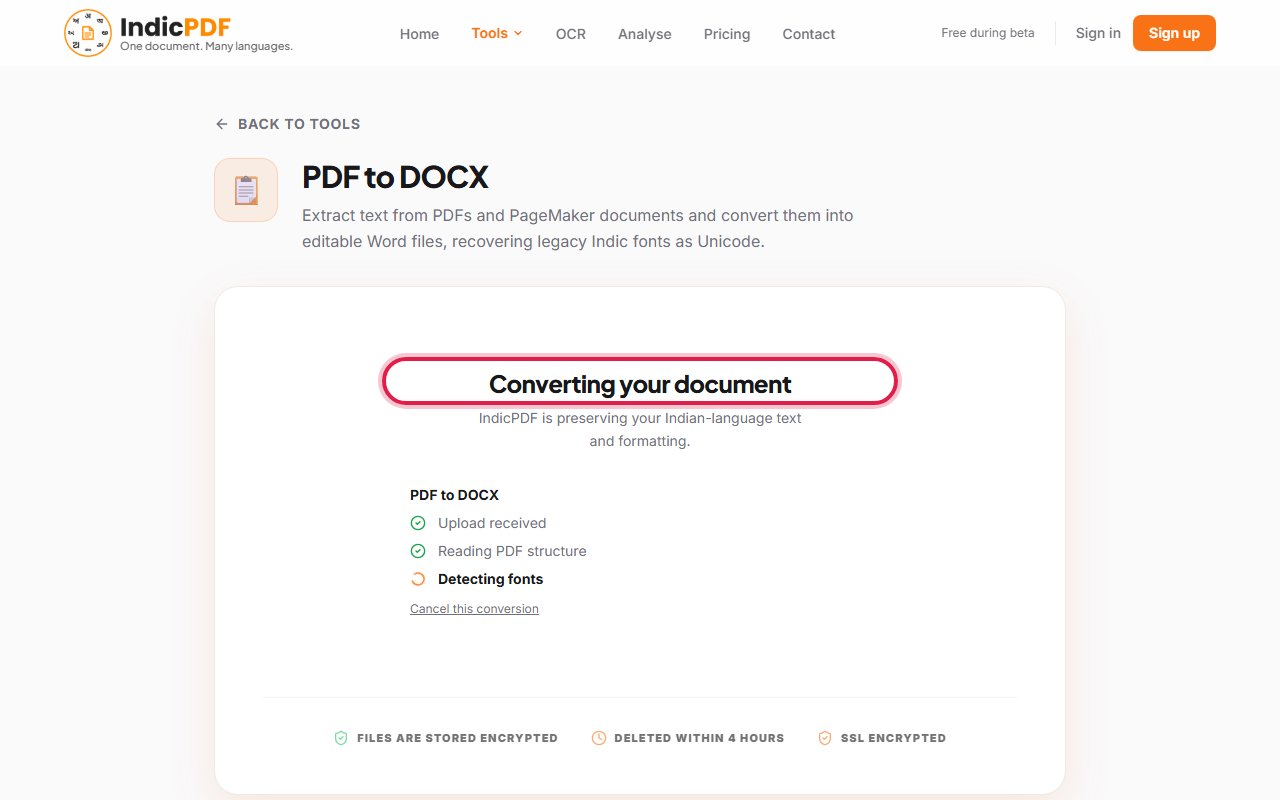
Step 2
We convert it
Indian-language text is read as Unicode: from the PDF’s own text, from an old font’s codes, or by OCR for a scan. The page shows each step as it happens.
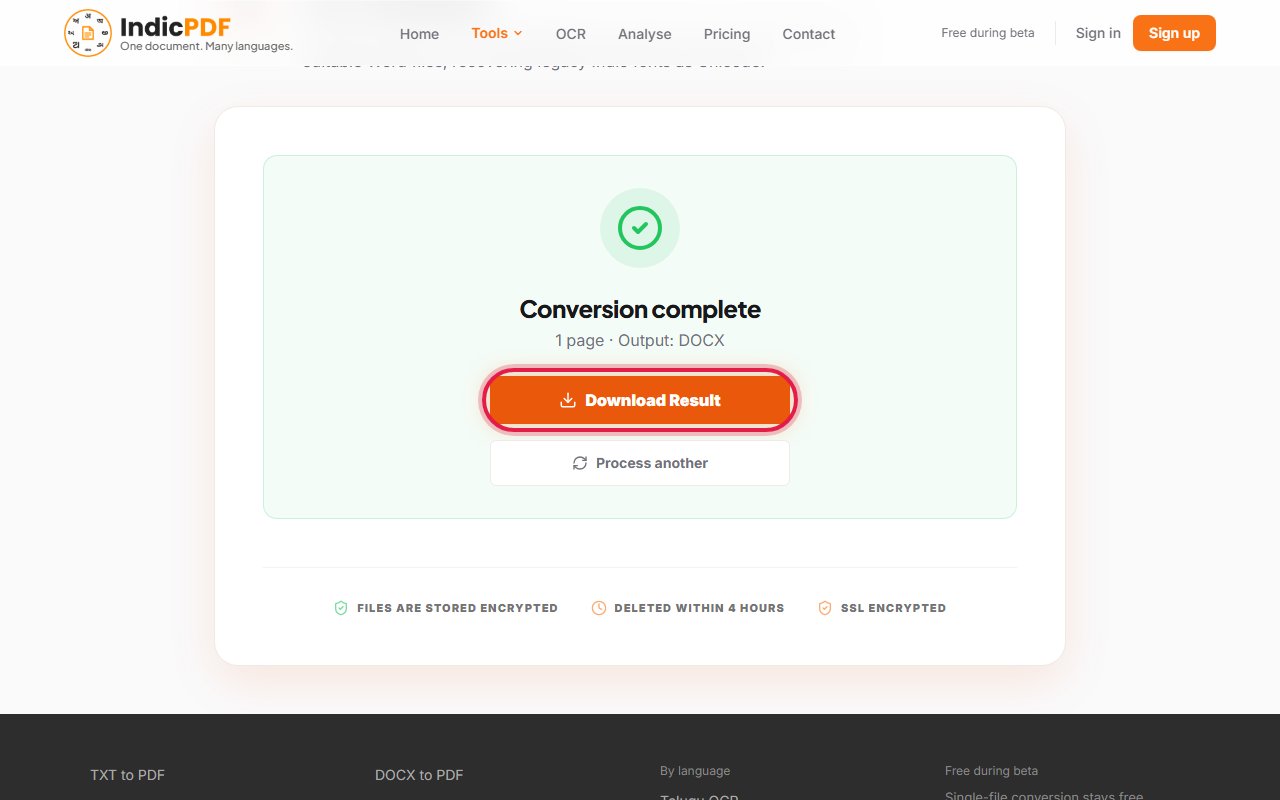
Step 3
Download and check
Download the result and check it against your original. The result page lists anything that needs a look, such as a number that did not come through.
Before and after
Lines from real documents typed in old fonts. On the left, the text the PDF itself carries, which is what copying it gets you. On the right, what IndicPDF reads, which is what the printed page shows.
In the PDF
fufonk lwpuk ls lEcfU/kr lekpkj i=ksa dh ,d izfr v/kksgLrk{kjh dk;kZy; esa fHktokus dk d’V djsaA
IndicPDF reads
निविदा सूचना से सम्बन्धित समाचार पत्रों की एक प्रति अधोहस्ताक्षरी कार्यालय में भिजवाने का कष्ट करें।
In the PDF
∑§„Ê Á∑§ ‚⁄U∑§Ê⁄U ‚÷Ë ’Ê…∏ ¬˝÷ÊÁflÃÙ¥ ∑‘§ ‚ÊÕ π«∏Ë „Ò–
IndicPDF reads
कहा कि सरकार सभी बाढ़ प्रभावितों के साथ खड़ी है।
In the PDF
‘hmamï´>mMr àmXo{eH$ ^mfm. {hMo JmoS>do Jmdo VodT>o H$‘rM! Aem ¶m
IndicPDF reads
महाराष्ट्राची प्रादेशिक भाषा. हिचे गोडवे गावे तेवढे कमीच! अशा या
In the PDF
Ùðó ÐððòçÃð¨î ¨îð ¡ðè÷
IndicPDF reads
मी नास्तिक का आहे
In the PDF
á düe÷#ês¡+q≈£î dü+ã+~Û+∫ s¡TdüTeTT @yÓTÆHê e]Ô+∫q#√
IndicPDF reads
ఈ సమాచారంనకు సంబంధించి రుసుము ఏమైనా వర్తించినచో
Measured, side by side
Plain text extraction is what copying from a PDF, or a converter that takes the PDF’s text as it is, gets. Where we have not measured a way of doing the job, the cell says so rather than guess.
| Document | IndicPDF | Plain text extraction | AI OCR | Retyping |
|---|---|---|---|---|
| Hindi PDFs typed in Kruti Dev, DevLys or Chanakya (50 real documents) | 93.0% of 147,394 words are Hindi words, read from the font | 2.5% of letters are Devanagari; 48 of the 50 give none | Not measured | Not measured |
| Scanned test pages in 12 Indian languages | 92.3–100% of characters read right, by language | No text: a scanned page is a picture | Not measured | Not measured |
| Old Telugu letterpress (14 proofread book pages) | 16.2% of characters wrong | No text: a scanned page is a picture | Not measured | Not measured |